Zero API Keys Required (BYOA)
ZeroVisual never calls LLM APIs directly. It runs 100% locally on your machine or CI/CD runner and outputs structured JSON or serves tools via standard MCP over stdio.
In an E2E Playwright test for https://www.wikipedia.org/, an unexpected +8px button padding shift causes the central #search-form to fail visual comparison. Without ZeroVisual, AI coding agents receive massive full-viewport screenshots overloaded with irrelevant footer links and empty whitespace. ZeroVisual isolates the defect, aligns to model-native vision tiles, and feeds clean, actionable context to your agent:
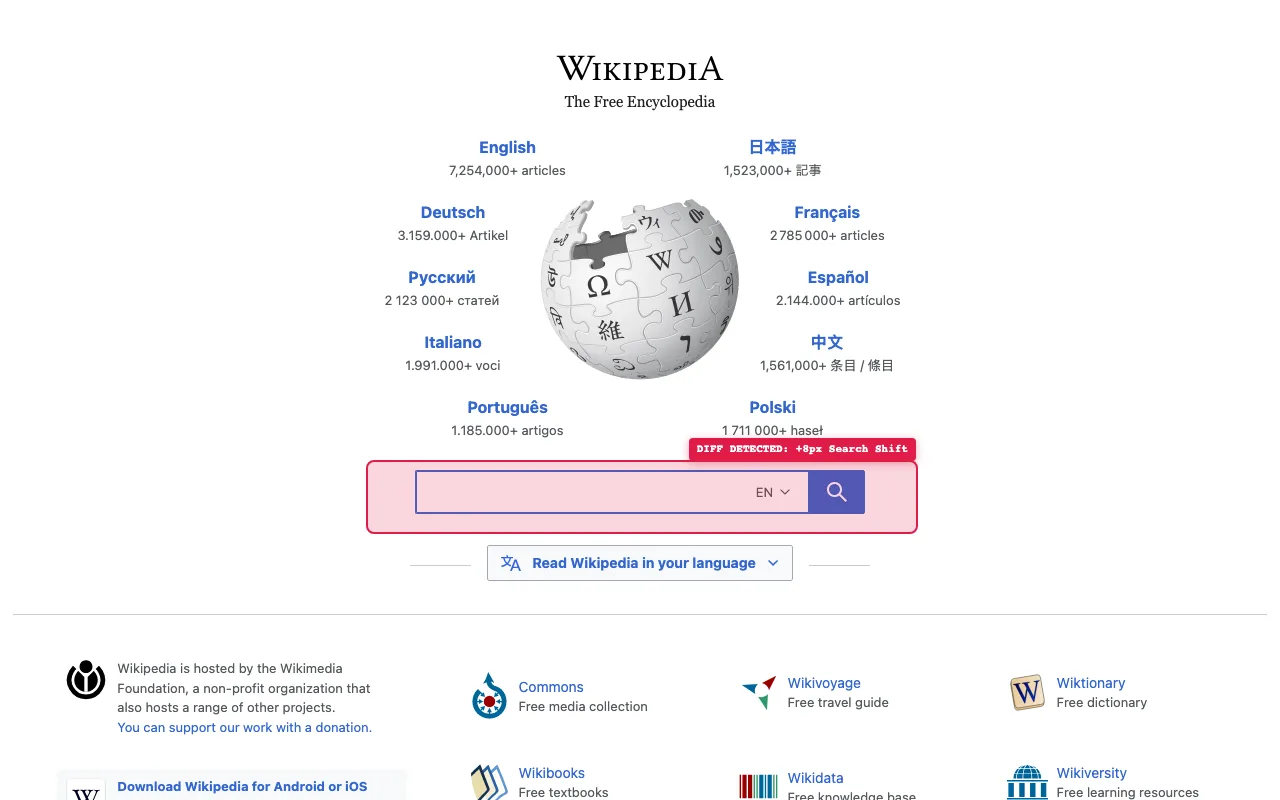
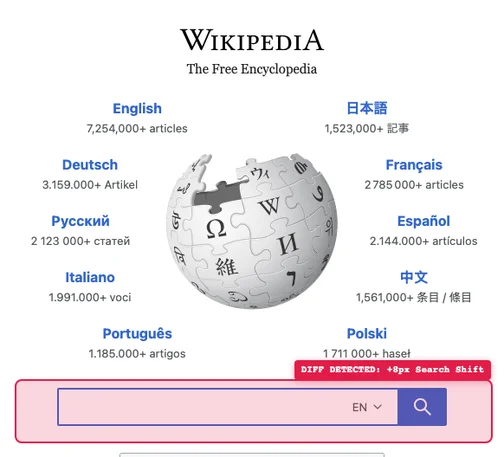
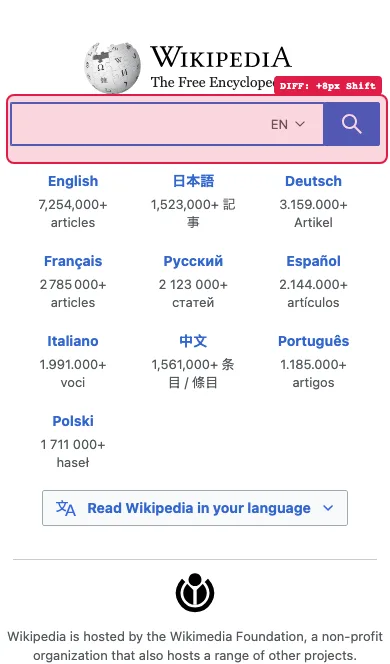
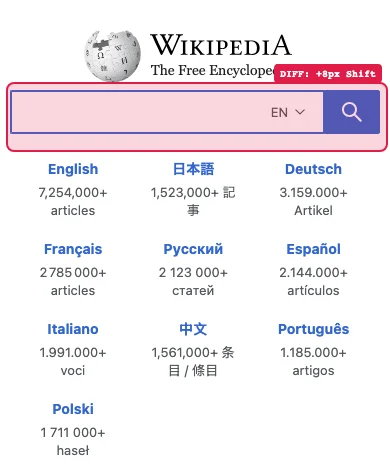
Instead of triggering separate AI reviews with disconnected full-page screenshots, ZeroVisual correlates Desktop Chrome and Mobile Safari under a single normalized testId in triage-ready.json:
{
  "testId": "tests/wikipedia.spec.ts:search-input",
  "status": "failed",
  "diff": {
    "desktop_chrome": {
      "tokens": 306,
      "tileGrid": "18x16",
      "image": "data:image/webp;base64,UklGRm..."
    },
    "mobile_safari": {
      "tokens": 238,
      "tileGrid": "14x17",
      "image": "data:image/webp;base64,UklGRn..."
    }
  },
  "totalTokens": 544,
  "savingsPercent": 77.1
}See exactly how much AI token spend and network bandwidth ZeroVisual saves on your visual test failures.
Zero API Keys Required (BYOA)
ZeroVisual never calls LLM APIs directly. It runs 100% locally on your machine or CI/CD runner and outputs structured JSON or serves tools via standard MCP over stdio.
Model-Aware Grid Math
Aligns failure diffs to exact Vision Transformer grids: 512px for OpenAI, 504px for Anthropic (28px patches), 768px/384px for Gemini, and 448px for Local models.
Multi-Viewport Aggregation
Correlates broken layouts across Desktop, Tablet, and Mobile viewports under a single normalized testId. Your AI agent diagnoses the breakpoint bug in one single prompt.
Scoped Semantic Context
Captures the component’s Playwright ariaSnapshot YAML and 14 computed layout CSS properties instead of dumping 100,000+ characters of raw HTML.
Heuristic UI Linter + Penpot
Objective math checks for WCAG 2.1 AA contrast ratios, 8pt spacing rhythm, and 44px tap targets, plus native SVG/JSON token diffing for open-source Penpot designs.
Dual Isolated Agent Skills
Separate zerovisual-regression (strict triage forensics) and zerovisual-design-qa (UI/UX coaching) skills to prevent prompt pollution and hallucinations.
| Metric | Raw Full-HD PNG (1920×1080) | ZeroVisual WebP (quality: 80) |
Engineering Advantage |
|---|---|---|---|
| Vision LLM Tokens | ~1,600 – 2,691 tokens / viewport | ~28 – 324 tokens / viewport | Up to ~90% token savings (crops & fits exact 1-tile grid) |
| Payload Size | ~4,000 KB (5.3 MB Base64) | ~35 KB (~47 KB Base64) | 99% byte reduction (instant IPC & network upload) |
| JSON Parse Time | ~100–300 ms (pipe congestion) | < 1 ms | Zero UI lag or event loop blocking in IDE |
| Model UI Readability | Full canvas noise | Isolated diff bounding box + 32px padding | Eliminates VLM hallucinations on subtle UI shifts |
Why Both Token Count and Network Bytes Matter:
- Vision Tokens (Pixel Dimensions): Vision Transformers (ViTs) calculate tokens based on geometric patch grids (e.g. Anthropic’s 28×28px patches, OpenAI’s 512×512px tiles)—not file bytes. Cropping and downscaling ensures failure diffs fit inside a single vision tile.
- Network Bytes (Payload Size): MCP over
stdioand HTTP API requests transfer images as Base64 strings (+33% byte expansion). Dropping images from 4 MB to 35 KB prevents Node.js JSON serialization bottlenecks and keeps your AI coding agent snappy.
Tested against a local LLM endpoint (RadixArk/Qwen3.8-27B-NVFP4 via SGLang) across 6 real-world UI visual regression scenarios:
👉 Read the full Empirical LLM Benchmark Report →
| Provider Setting | Target Max Bounding Box | Vision Grid Mechanics | Approx. Token Cost per Diff |
|---|---|---|---|
openai |
512 × 512 px |
Fits inside 1 standard OpenAI 512px tile |
~85 – 255 tokens |
anthropic |
504 × 504 px |
Exact 18 × 18 grid of 28×28 px patches |
~28 – 324 tokens |
gemini |
768 × 768 px |
Fits 1 native Gemini tile | ~258 tokens |
gemini (lowTokenMode) |
384 × 384 px |
Sub-384px single base tile optimization | ~258 tokens (ultra-fast) |
local |
448 × 448 px (configurable) |
Optimized for local VLMs (28px / 14px patch ViTs) |
Local compute |